Mostrando entradas con la etiqueta Reconocimiento de Imágenes. Mostrar todas las entradas

jueves, 28 de agosto de 2014

It's Time to Take Artificial Intelligence Seriously

No Longer an Academic Curiosity, It Now Has Measurable Impact on Our Lives

A still from "2001: A Space Odyssey" with Keir Dullea reflected in the lens of HAL's "eye." MGM / POLARIS / STANLEY KUBRICK

The age of intelligent machines has arrived—only they don't look at all like we expected. Forget what you've seen in movies; this is no HAL from "2001: A Space Odyssey," and it's certainly not Scarlett Johansson's disembodied voice in "Her." It's more akin to what happens when insects, or even fungi, do when they "think." (What, you didn't know that slime molds can solve mazes?)

Artificial intelligence has lately been transformed from an academic curiosity to something that has measurable impact on our lives. Google Inc. used it to increase the accuracy of voice recognition in Android by 25%. The Associated Press is printing business stories written by it. Facebook Inc. is toying with it as a way to improve the relevance of the posts it shows you.

What is especially interesting about this point in the history of AI is that it's no longer just for technology companies. Startups are beginning to adapt it to problems where, at least to me, its applicability is genuinely surprising.

Take advertising copywriting. Could the "Mad Men" of Don Draper's day have predicted that by the beginning of the next century, they would be replaced by machines? Yet a company called Persado aims to do just that.

Persado does one thing, and judging by its client list, which includes Citigroup Inc. and Motorola Mobility, it does it well. It writes advertising emails and "landing pages" (where you end up if you click on a link in one of those emails, or an ad).

Here's an example: Persado's engine is being used across all of the types of emails a top U.S. wireless carrier sends out when it wants to convince its customers to renew their contracts, upgrade to a better plan or otherwise spend money.

Traditionally, an advertising copywriter would pen these emails; perhaps the company would test a few variants on a subset of its customers, to see which is best.

But Persado's software deconstructs advertisements into five components, including emotion words, characteristics of the product, the "call to action" and even the position of text and the images accompanying it. By recombining them in millions of ways and then distilling their essential characteristics into eight or more test emails that are sent to some customers, Persado says it can effectively determine the best possible come-on.

"A creative person is good but random," says Lawrence Whittle, head of sales at Persado. "We've taken the randomness out by building an ontology of language."

The results speak for themselves: In the case of emails intended to convince mobile subscribers to renew their plans, initial trials with Persado increased click-through rates by 195%, the company says.

Here's another example of AI becoming genuinely useful: X.ai is a startup aimed, like Persado, at doing one thing exceptionally well. In this case, it's scheduling meetings. X.ai's virtual assistant, Amy, isn't a website or an app; she's simply a "person" whom you cc: on emails to anyone with whom you'd like to schedule a meeting. Her sole "interface" is emails she sends and receives—just like a real assistant. Thus, you don't have to bother with back-and-forth emails trying to find a convenient time and available place for lunch. Amy can correspond fluidly with anyone, but only on the subject of his or her calendar. This sounds like a simple problem to crack, but it isn't, because Amy must communicate with a human being who might not even know she's an AI, and she must do it flawlessly, says X.ai founder Dennis Mortensen.

E-mail conversations with Amy are already quite smooth. Mr. Mortensen used her to schedule our meeting, naturally, and it worked even though I purposely threw in some ambiguous language about the times I was available. But that is in part because Amy is still in the "training" stage, where anything she doesn't understand gets handed to humans employed by X.ai.

It sounds like cheating, but every artificially intelligent system needs a body of data on which to "train" initially. For Persado, that body of data was text messages sent to prepaid cellphone customers in Europe, urging them to re-up their minutes or opt into special plans. For Amy, it's a race to get a body of 100,000 email meeting requests. Amusingly, engineers at X.ai thought about using one of the biggest public database of emails available, the Enron emails, but there is too much scheming in them to be a good sample.

Both of these systems, and others like them, work precisely because their makers have decided to tackle problems that are as narrowly defined as possible. Amy doesn't have to have a conversation about the weather—just when and where you'd like to schedule a meeting. And Persado's system isn't going to come up with the next "Just Do It" campaign.

This is where some might object that the commercialized vision for AI isn't intelligent at all. But academics can't even agree on where the cutoff for "intelligence" is in living things, so the fact that these first steps toward economically useful artificial intelligence lie somewhere near the bottom of the spectrum of things that think shouldn't bother us.

We're also at a time when it seems that advances in the sheer power of computers will lead to AI that becomes progressively smarter. So-called deep-learning algorithms allow machines to learn unsupervised, whereas both Persado and X.ai's systems require training guided by humans.

Last year Google showed that its own deep-learning systems could learn to recognize a cat from millions of images scraped from the Internet, without ever being told what a cat was in the first place. It's a parlor trick, but it isn't hard to see where this is going—the enhancement of the effectiveness of knowledge workers. Mr. Mortensen estimates there are 87 million of them in the world already, and they schedule 10 billion meetings a year. As more tools tackling specific portions of their job become available, their days could be filled with the things that only humans can do, like creativity.

"I think the next Siri is not Siri; it's 100 companies like ours mashed into one," says Mr. Mortensen.

—Follow Christopher Mims on Twitter @Mims or write to him atchristopher.mims@wsj.com.

By CHRISTOPHER MIMS
Aug. 24, 2014

sábado, 16 de agosto de 2014

Google buys city guides app Jetpac, support to end on September 15


Google has acquired the team behind Jetpac, an iPhone app for crowdsourcing city guides from public Instagram photos.

The app will be pulled from the App Store in coming days, and support for the service will be discontinued on September 15.

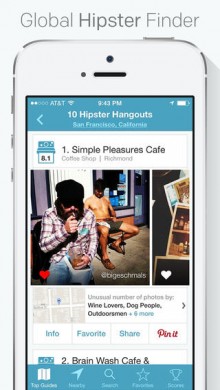
Jetpac’s deep learning software used a nifty trick of scanning our photos to evaluate businesses and venues around town. As MIT Technology Review notes, the app could tell whether visitors were tourists, whether a bar is dog-friendly and how fancy a place was.

It even employed humans to find hipster spots by training the system to count the number of mustaches and plaid shirts.

Interestingly, Jetpac’s technology was inspired by Google researcher Geoffrey Hinton, so it makes perfect sense for Google to bring the startup into its fold. If this means that Google Now will gain the ability to automatically alert me when I’m entering a hipster-infested area, then I’m an instant fan.

Jetpac also built two iOS apps that tapped into its Deep Belief neural network to offer users object recognition.

“Imagine all photos tagged automatically, the ability to search the world by knowing what is in the world’s shared photos, and robots that can see like humans,” the App Store description for its Spotter app reads. If that’s not a Googly description, I don’t know what is.

➤ Jetpac

(h/t Ouriel Ohayon)

Thumbnail image credit: GEORGES GOBET/AFP/Getty Images


ORIGINAL: The Next Web

domingo, 23 de marzo de 2014

Zuckerberg and Musk back software startup that mimics human learning

San Francisco startup Vicarious aims to create 'a computer that thinks like a person except it doesn't need to eat or sleep'

Vicarious is developing 'machine learning software based on the computational principles of the human brain'. Photograph: Sebastian Kaulitzki / Alamy/Alamy

Some of Silicon Valley’s biggest names are backing a hitherto low-profile tech startup that aims to recreate the human neocortex as computer code.

Vicarious, a four-year-old San Francisco-based startup, claims to be “building software that thinks and learns like a human”. According to the Wall Street Journal Facebook's Mark Zuckerberg and Tesla's Elon Musk have just invested $40m in the company.

They join Peter Thiel, a PayPal billionaire, whose Founders Fund targets cutting edge technology. Ashton Kutcher, actor and tech investor, is also investing, as is Facebook co-founder Dustin Moskovitz.

The neocortex is the outer layer of the cerebral hemispheres and in humans is crucial to the use of the senses as well as activities such as language, motor commands and spatial reasoning.

According to the company’s website, Vicarious is developing “machine learning software based on the computational principles of the human brain. Our first technology is a visual perception system that interprets the contents of photographs and videos in a manner similar to humans. Powering this technology is a new computational paradigm we call the Recursive Cortical Network.”

The company has already managed to create software that will solve Captcha, the online tests used by many websites to supposedly identify humans from computers. Company founder Scott Phoenix told the WSJ that if they are successful, Vicarious will have created "a computer that thinks like a person except it doesn't need to eat or sleep".

Phoenix said his aim was to create a computer that can understand not just shapes and objects but the textures associated with them. He said he hopes Vicarious’s computers will learn to how to cure diseases and create cheap, renewable energy, as well as performing the jobs that employ most human beings. “We tell investors that right now, human beings are doing a lot of things that computers should be able to do,” he said.

The investment comes amid a boom in funding for artificial intelligence ventures, In January IBM announced it was investing more than $1bn to create the Watson Group, a 2,000-employee division dedicated to developing its self-learning super-computer. The money includes $100m to fund startups that find creative uses for Watson.

Earlier this week IBM announced a partnership with the New York Genome Center that will attempt to use Watson to identify the genetic components of brain cancer.

ORIGINAL: The Guardian
Dominic Rushe in New York
21 March 2014

miércoles, 19 de marzo de 2014

Facebook Creates Software That Matches Faces Almost as Well as You Do

Facebook’s new AI research group reports a major improvement in face-processing software.

Why It Matters

Advances in the relatively new artificial-intelligence field known as deep learning could fundamentally reshape what computers can do.

Asked whether two unfamiliar photos of faces show the same person, a human being will get it right 97.53 percent of the time. New software developed by researchers at Facebook can score 97.25 percent on the same challenge, regardless of variations in lighting or whether the person in the picture is directly facing the camera.

That’s a significant advance over previous face-matching software, and it demonstrates the power of a new approach to artificial intelligence known as deep learning, which Facebook and its competitors have bet heavily on in the past year (see “Deep Learning”). This area of AI involves software that uses networks of simulated neurons to learn to recognize patterns in large amounts of data.

“You normally don’t see that sort of improvement,” says Yaniv Taigman, a member of Facebook’s AI team, a research group created last year to explore how deep learning might help the company (see “Facebook Launches Advanced AI Effort”). “We closely approach human performance,” says Taigman of the new software. He notes that the error rate has been reduced by more than a quarter relative to earlier software that can take on the same task.

Head turn: DeepFace uses a 3-D model to rotate faces, virtually, so that they face the camera. Image (a) shows the original image, and (g) shows the final, corrected version.

Facebook’s new software, known as DeepFace, performs what researchers call facial verification (it recognizes that two images show the same face), not facial recognition (putting a name to a face). But some of the underlying techniques could be applied to that problem, says Taigman, and might therefore improve Facebook’s accuracy at suggesting whom users should tag in a newly uploaded photo.

However, DeepFace remains purely a research project for now. Facebook released a research paper on the project last week, and the researchers will present the work at the IEEE Conference on Computer Vision and Pattern Recognition in June. “We are publishing our results to get feedback from the research community,” says Taigman, who developed DeepFace along with Facebook colleagues Ming Yang and Marc’Aurelio Ranzato and Tel Aviv University professor Lior Wolf.

DeepFace processes images of faces in two steps. First it corrects the angle of a face so that the person in the picture faces forward, using a 3-D model of an “average” forward-looking face. Then the deep learning comes in as a simulated neural network works out a numerical description of the reoriented face. If DeepFace comes up with similar enough descriptions from two different images, it decides they must show the same face.

The performance of the final software was tested against a standard data set that researchers use to benchmark face-processing software, which has also been used to measure how humans fare at matching faces.

Neeraj Kumar, a researcher at the University of Washington who has worked on face verification and recognition, says that Facebook’s results show how finding enough data to feed into a large neural network can allow for significant improvements in machine-learning software. “I’d bet that a lot of the gain here comes from what deep learning generally provides: being able to leverage huge amounts of outside data in a much higher-capacity learning model,” he says.

The deep-learning part of DeepFace consists of nine layers of simple simulated neurons, with more than 120 million connections between them. To train that network, Facebook’s researchers tapped a tiny slice of data from their company’s hoard of user images—four million photos of faces belonging to almost 4,000 people. “Since they have access to lots of data of this form, they can successfully train a high-capacity model,” says Kumar.

ORIGINAL: Technology Review
By Tom Simonite
March 17, 2014

viernes, 20 de diciembre de 2013

Computer Searches Web 24/7 To Analyze Images and Teach Itself Common Sense


A computer program called the Never Ending Image Learner (NEIL) is running 24 hours a day at Carnegie Mellon University, searching the Web for images, doing its best to understand them on its own and, as it builds a growing visual database, gathering common sense on a massive scale.

NEIL leverages recent advances in computer vision that enable computer programs to identify and label objects in images, to characterize scenes and to recognize attributes, such as colors, lighting and materials, all with a minimum of human supervision. In turn, the data it generates will further enhance the ability of computers to understand the visual world.

But NEIL also makes associations between these things to obtain common sense information that people just seem to know without ever saying — that cars often are found on roads, that buildings tend to be vertical and that ducks look sort of like geese. Based on text references, it might seem that the color associated with sheep is black, but people — and NEIL — nevertheless know that sheep typically are white.

“Images are the best way to learn visual properties,” said Abhinav Gupta, assistant research professor in Carnegie Mellon’s Robotics Institute. “Images also include a lot of common sense information about the world. People learn this by themselves and, with NEIL, we hope that computers will do so as well.”

A computer cluster has been running the NEIL program since late July and already has analyzed three million images, identifying 1,500 types of objects in half a million images and 1,200 types of scenes in hundreds of thousands of images. It has connected the dots to learn 2,500 associations from thousands of instances.

The public can now view NEIL’s findings at the project website, www.neil-kb.com.

The research team, including Xinlei Chen, a Ph.D. student in CMU’s Language Technologies Institute, and Abhinav Shrivastava, a Ph.D. student in robotics, will present its findings on Dec. 4 at the IEEE International Conference on Computer Vision in Sydney, Australia

One motivation for the NEIL project is to create the world’s largest visual structured knowledge base, where objects, scenes, actions, attributes and contextual relationships are labeled and catalogued.

“What we have learned in the last 5-10 years of computer vision research is that the more data you have, the better computer vision becomes,” Gupta said.

Some projects, such as ImageNet and Visipedia, have tried to compile this structured data with human assistance. But the scale of the Internet is so vast — Facebook alone holds more than 200 billion images — that the only hope to analyze it all is to teach computers to do it largely by themselves.

Shrivastava said NEIL can sometimes make erroneous assumptions that compound mistakes, so people need to be part of the process. A Google Image search, for instance, might convince NEIL that “pink” is just the name of a singer, rather than a color.

“People don’t always know how or what to teach computers,” he observed. “But humans are good at telling computers when they are wrong.”

People also tell NEIL what categories of objects, scenes, etc., to search and analyze. But sometimes, what NEIL finds can surprise even the researchers. It can be anticipated, for instance, that a search for “apple” might return images of fruit as well as laptop computers. But Gupta and his landlubbing team had no idea that a search for F-18 would identify not only images of a fighter jet, but also of F18-class catamarans.

As its search proceeds, NEIL develops subcategories of objects – tricycles can be for kids, for adults and can be motorized, or cars come in a variety of brands and models. And it begins to notice associations – that zebras tend to be found in savannahs, for instance, and that stock trading floors are typically crowded.

NEIL is computationally intensive, the research team noted. The program runs on two clusters of computers that include 200 processing cores.

This research is supported by the Office of Naval Research and Google Inc.

Related People 

Abhinav Gupta
Abhinav Shrivastava

Related Labs 
Computer Graphics Lab


ORIGINAL: Carnegie Mellon
Computer Graphics Lab
November 20, 2013

martes, 30 de julio de 2013

Artificial Intelligence Is the Most Important Technology of the Future

ORIGINAL: Maria Konovalenko Blog
Maria Konovalenko
July 30, 2013 · 16:36


Artificial Intelligence is a set of tools that are driving forward key parts of the futurist agenda, sometimes at a rapid clip. The last few years have seen a slew of surprising advances: 
  • the IBM supercomputer Watson, which beat two champions of Jeopardy!; 
  • self-driving cars that have logged over 300,000 accident-free miles and are officially legal in three states; and 
  • statistical learning techniques are conducting pattern recognition on complex data sets from consumer interests to trillions of images. 
In this post, I’ll bring you up to speed on what is happening in AI today, and talk about potential future applications. Any brief overview of AI will be necessarily incomplete, but I’ll be describing a few of the most exciting items.

The key applications of Artificial Intelligence are in any area that involves more data than humans can handle on our own, but which involves decisions simple enough that an AI can get somewhere with it. Big data, lots of little rote operations that add up to something useful. An example is image recognition; by doing rigorous, repetitive, low-level calculations on image features, we now have services like Google Goggles, where you take an image of something, say a landmark, and Google tries to recognize what it is. Services like these are the first stirrings of Augmented Reality (AR).

It’s easy to see how this kind of image recognition can be applied to repetitive tasks in biological research. One such difficult task is in brain mapping, an area that underlies dozens of transhumanist goals. The leader in this area is Sebastian Seung at MIT, who develops software to automatically determine the shape of neurons and locate synapses. Seung developed a fundamentally new kind of computer vision for automating work towards building connectomes, which detail the connections between all neurons. These are a key step to building computers that simulate the human brain.

As an example of how difficult it is to build a connectome without AI, consider the case of the flatworm, C. elegans, the only completed connectome to date. Although electron microscopy was used to exhaustively map the brain of this flatworm in the 1970s and 80s, it took more than a decade of work to piece this data into a full map of the flatworm’s brain. This is despite that brain containing just 7000 connections between 300 neurons. By comparison, the human brain contains 100 trillion connections between 100 billion neurons. Without sophisticated AI, mapping it will be hopeless.

There’s another closely related area that depends on AI to make progress; cognitive prostheses. These are brain implants that can perform the role of a part of the brain that has been damaged. Imagine a prosthesis that restores crucial memories to Alzheimer’s patients. The feasibility of a prosthesis of the hippocampus, part of the brain responsible for memory, was proven recently by Theodore Berger at the University of Southern California. A rat with its hippocampus chemically disabled was able to form new memories with the aid of an implant.

The way these implants are built is by carefully recording the neural signals of the brain and making a device that mimics the way they work. The device itself uses an artificial neural network, which Berger calls a High-density Hippocampal Neuron Network Processor. Painstaking observation of the brain region in question is needed to build a model detailed enough to stand in for the original. Without neural network techniques (a subcategory of AI) and abundant computing power, this approach would never work.

Bringing the overview back to more everyday tech, consider all the AI that will be required to make the vision of Augmented Reality mature. AR, as exemplified by Google Glass, uses computer glasses to overlay graphics on the real world. For the tech to work, it needs to quickly analyze what the viewer is seeing and generate graphics that provide useful information. To be useful, the glasses have to be able to identify complex objects from any direction, under any lighting conditions, no matter the weather. To be useful to a driver, for instance, the glasses would need to identify roads and landmarks faster and more effectively than is enabled by any current technology. AR is not there yet, but probably will be within the next ten years. All of this falls into the category of advances in computer vision, part of AI.

Finally, let’s consider some of the recent advances in building AI scientists. In 2009, “Adam” became the first robot to discover new scientific knowledge, having to do with the genetics of yeast. The robot, which consists of a small room filled with experimental equipment connected to a computer, came up with its’ own hypothesis and tested it. Though the context and the experiment were simple, this milestone points to a new world of robotic possibilities. This is where the intersection between AI and other transhumanist areas, such as life extension research, could become profound.

Many experiments in life science and biochemistry require a great deal of trial and error. Certain experiments are already automated with robotics, but what about computers that formulate and test their own hypotheses? Making this feasible would require the computer to understand a great deal of common sense knowledge, as well as specialized knowledge about the subject area. Consider a robot scientist like Adam with the object-level knowledge of the Jeopardy!-winning Watson supercomputer. This could be built today in theory, but it will probably be a few years before anything like it is built in practice. Once it is, it’s difficult to say what the scientific returns could be, but they could be substantial. We’ll just have to build it and find out.

That concludes this brief overview. There are many other interesting trends in AI, but machine vision, cognitive prostheses, and robotic scientists are among the most interesting, and relevant to futurist goals.

I would like to thank Michael Anissimov, a fellow transhumanist and author of the Accelerating Future blog, for contributing this piece.